
Open Claude's model picker and you find four names: Haiku, Sonnet, Opus and Fable. Anthropic ranks these Claude models from lightest to most powerful, which leads to a logical conclusion: pick the biggest one, since it is right there. That is rarely the right choice, and often a bad calculation.
To check, I gave exactly the same prompts to all four models, in the same interface, and compared what came out. It is all in the video (in French), in six minutes. This article goes over the results, adds what I did not have time to cover on screen (the plans, the prices, the effort setting) and ends with a tool that tells you which model and which effort level to set for your task.
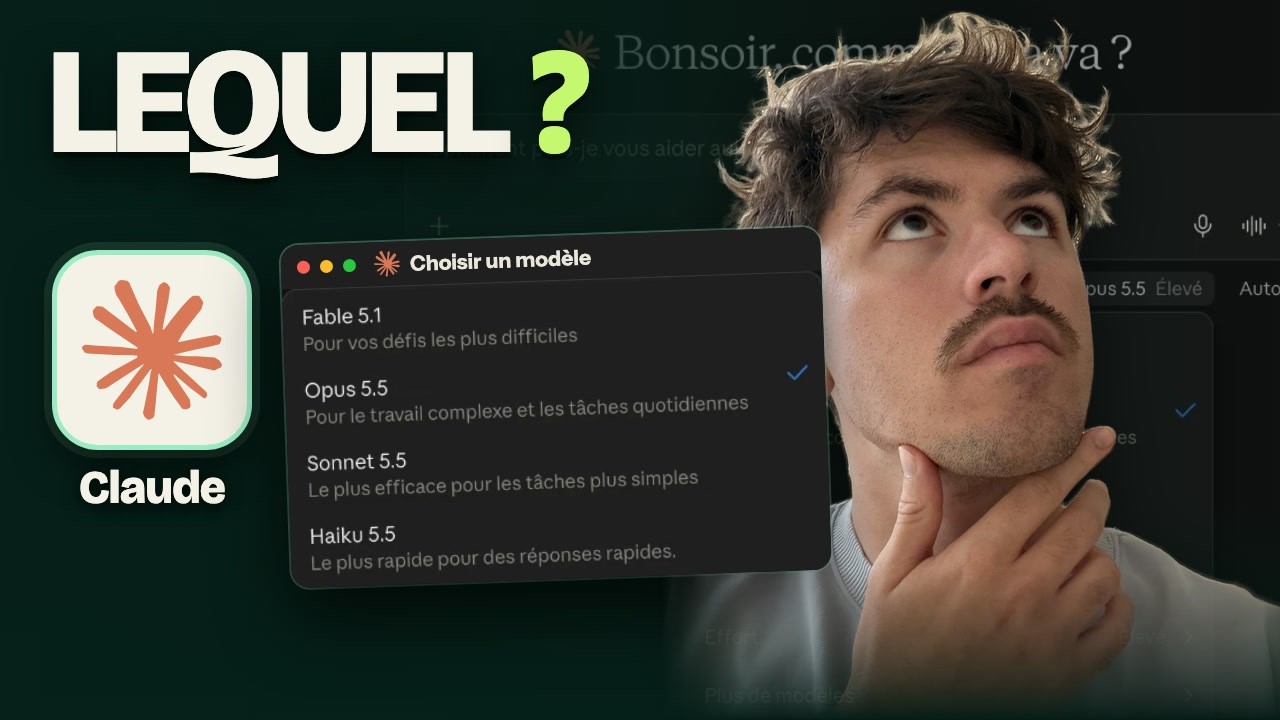 Haiku, Sonnet, Opus or Fable: the comparison in 5:57 (in French)
Video chapters (in French): 0:00 the short answer · 0:41 test 1, an impossible schedule · 1:23 test 2, building a real tool · 2:56 what the big models are for · 4:16 what about Mythos? · 4:45 effort, the hidden setting · 5:49 summing up.
Key takeaways
- Claude offers four models in October 2026: Haiku 4.5, Sonnet 5.5, Opus 5.5 and Fable 5.1, from fastest to most capable.
- On the free plan, I stick with Sonnet. On a paid plan, I set Opus as my default: it does almost everything Fable does, for a fraction of the cost.
- On a trick question (an impossible schedule), all four models found that no solution existed, Haiku included.
- On a freelance day rate calculator, Opus had the best business insight. Fable delivered the most technical dashboard, without that insight.
- The big models make a difference on multi-step tasks (connectors, skills, files) and on long code, not on a single question.
- The effort level does not make the model smarter: it gives it more thinking time, and eats into your usage limit accordingly.
Which Claude model to choose: the short answer
If you only read one paragraph: on the free plan, Sonnet; on a paid plan, Opus. Haiku for small repetitive tasks, Fable for large coding projects or long tasks that Opus cannot finish.
| Model | What for | Plan | How I use it |
|---|---|---|---|
| Haiku 4.5 | The fastest: short questions, rephrasing, sorting, repetitive tasks | All, including Free | Simple questions, when speed matters |
| Sonnet 5.5 | Everyday use: writing, summarizing, documents, spreadsheets, simple code | All, including Free | My default on the free plan |
| Opus 5.5 | Complex work: long reasoning, analysis, multi-step tasks | Pro and above | My default on a paid plan |
| Fable 5.1 | The most capable: ambitious code, very long and demanding tasks | Max and Premium seats; Pro with usage credits | Only when Opus hits its ceiling |
Why not use Fable all the time, since it is the most powerful? Because it is often too heavy for the task at hand. It thinks longer, costs significantly more and, on an ordinary request, does not deliver a better result than Opus. Anthropic says as much in its own way: by its own measurements, Opus 5.5 reaches Fable 5.1's level on most tasks. The two tests below show it in practice.
Lineup and prices checked on October 14, 2026
In the Claude app and on Anthropic's pricing page. Version names change several times a year, the logic of the choice much less so. For details on each plan, see Claude subscription pricing and plans.
The four Claude models at a glance
The four models share the same interface, the same tools and the same connectors. What changes: speed, reasoning depth, and the price of every word produced. On the API, the gap is plain to see:
| Model | Input, per million tokens | Output, per million tokens | Compared to Haiku |
|---|---|---|---|
| Haiku 4.5 | $1 | $5 | Baseline |
| Sonnet 5.5 | $2 | $10 | × 2 |
| Opus 5.5 | $4 | $20 | × 4 |
| Fable 5.1 | $10 | $50 | × 10 |
With a subscription, you do not see these prices, but you still pay them: each message eats into your session limit in proportion to the model and effort level you choose. One exchange with Fable at maximum effort weighs much more than one with Sonnet at medium effort. That is why choosing a model is not just about quality: it is also about how long you can keep working through the day.
The free plan gives access to Sonnet and Haiku. Opus comes with Pro, at $20 per month ($17 billed annually). Fable is included in Max ($100 or $200 per month), up to half of the weekly limit, and can be used on Pro with usage credits billed on top. I cover what the free plan lets you do in Claude AI for free.
Test 1: an impossible schedule
The first test was deliberately rigged. I asked each model to fit a series of appointments into one week, with availability and sequencing constraints that, taken together, rule each other out. No valid schedule exists. So the right answer is not a schedule: it is "this is not possible, and here is why".
This is the kind of question where a weak model tends to make things up: it wants to help, so it produces a schedule that looks clean and quietly breaks a constraint. The best safeguard is still to give the model all the data in the message: on this point, context matters more than how the prompt is worded.
Result: all four got it. Haiku, the smallest, identified the conflict, explained that no solution met every constraint, then asked me which one to relax. Sonnet, Opus and Fable reached the same conclusion, with more or less detailed explanations.
What this test really tells you
On a well-framed question, with all the data in the message, even Claude's smallest model reasons correctly. The gap between models does not show up in the logic of a single question. It shows up elsewhere.
Test 2: building a freelance day rate calculator
The second test was closer to real work. I asked each model to build a calculator that works out the day rate at which a freelancer becomes profitable. A small app, usable right inside the conversation.
| Model | What it delivered | What sets it apart |
|---|---|---|
| Haiku | A simple, working calculator: day rate, billed days, monthly costs, a slider, a live calculation | It does the job, nothing more |
| Sonnet | Roughly the same thing, with a different design | Nothing decisive compared to Haiku |
| Opus | The same base, plus a setting: time off spread over the year, or concentrated in summer and at year end | The only one to think of August with no income |
| Fable | A more technical financial dashboard, more precise on some calculations | More impressive, but without the time-off idea |
The detail that makes the difference is Opus's setting. A freelancer who takes three weeks off in August earns nothing that month. Without this parameter, the chart shows August in the red and the calculated day rate is too low. Opus anticipated it without being asked: the day rate adjusts and the chart smooths income over the year. That is a business insight, not a technical feat.
Fable, for its part, produced the richest interface, with a finance dashboard look. More precise on a few points, but it missed the time-off question. For this task, it brings nothing that justifies paying ten times Haiku's price and two and a half times Opus's.
My verdict after both tests
On single requests, all four models hold up. The difference shows in judgment, not in raw capability.
- Opus: the best balance of quality and cost, and the most useful initiative
- Sonnet: more than enough for everyday use, for free
- Haiku: reliable on a well-framed question
- Fable: oversized for an ordinary request
- Haiku: avoid it as soon as the task drags on
Default: Sonnet on Free, Opus on a paid plan Tests run in the Claude app, October 2026
Opus vs Sonnet: what the big models are really for
If Haiku or Sonnet do the job on these two tests, why pay for Opus or Fable? Because my tests are one-off requests. The real home ground of the big models is chaining: a task that requires using several tools one after the other, without losing the thread.
An example from my day-to-day SEO work. I ask Claude to write an article my way, based on data pulled by the connectors plugged into my account, then to file the result neatly in a tracking Google Sheet. That is about ten steps: reading my instructions, calling the right connectors, applying a writing skill, checking, writing to the right place in the spreadsheet.
On this kind of chain, the difference between models becomes clear:
- Haiku and Sonnet struggle more. They ask more questions, stop halfway, and can even overwrite a column or damage a file while trying to help.
- Opus and Fable hold the chain from end to end, pick the right tools in the right order and check what they have written.
That is exactly what Claude Cowork and Claude Code do: delegate a whole task rather than ask a question. The longer the task and the more it touches real files, the more the model matters.
The rule I follow
As soon as Claude is allowed to write somewhere (a spreadsheet, a website, a folder), I switch to Opus. A Sonnet mistake in a chat answer gets fixed when you reread it. A mistake in a shared file gets discovered too late.
When to bring out Fable
Fable has its place, but it is a narrow one. I bring it out in two cases:
- Building an app. When I build a tool through vibe coding, that is, describing what I want and letting Claude write the code, Fable goes much further than Sonnet: more files that fit together, fewer back-and-forths to fix things.
- The task Opus cannot finish. Very long reasoning, a large volume of documents to cross-reference, a problem where Opus goes around in circles. That is where Fable is worth its price.
Outside these cases, Fable eats your usage for a result you could not have told apart from Opus's. On Pro, every use of Fable also goes through paid credits.
What about Mythos?
You may have come across the name Claude Mythos, presented as Anthropic's most powerful model. You will not find it in the model picker, even with the Max subscription at $200 per month. I checked on my own account.
The reason is simple: Mythos 5.1 is the same model as Fable 5.1. The difference lies in the safeguards. Fable ships with additional protections, especially in cybersecurity. Mythos has them lifted, and access is restricted to vetted organizations that need it for their work, in cybersecurity and the life sciences. So it is not a model "above" Fable that the general public is waiting for: it is Fable, unrestricted, for supervised uses. The story of this launch is in the origins of Claude AI.
Effort: the setting nobody looks at
Beneath the choice of model lies a second setting, often ignored: the effort level. In the picker, each model offers five: low, medium, high, extra and max. In Claude Code, one more notch appears above them.
Contrary to what its name suggests, effort does not make the model smarter. It gives it more time: more thinking before answering, more searching, more checking. Like someone concentrating harder, with the same abilities.
| Effort | What it changes | When I use it |
|---|---|---|
| Low | Fast answer, minimal thinking | Rephrasing, translating, answering a simple question |
| Medium | The right balance for everyday use | Writing, summarizing, analyzing a short document |
| High | Deeper thinking, more checks | An analysis that matters, a multi-step task |
| Extra | Much longer and more expensive | A hard problem where high effort failed |
| Max | The model takes all the time it deems useful | A big project, launched knowing what it will cost |
The difference in duration is real. On a heavy task, an answer at low effort can arrive in two minutes when the same request at max effort will take thirty minutes, or even an hour. The answer will usually be more accurate and more thorough, but it will also use much more of your limit.
Watch out on the $20 subscription
On Pro, a few requests at max effort are enough to drain your five-hour session. Keep medium effort as the default and only go up when the answer falls short. The right reflex: change the effort level before changing the model.
My rule fits in one sentence: choose the model based on the nature of the task, and the effort based on what is at stake. A simple but important task means Sonnet at high effort. A complex but exploratory task means Opus at medium effort. The tool below does this reasoning for you.
My everyday settings
To wrap up, here is what I actually use, on a Max subscription, over a working day:
- Opus by default, at medium effort, for almost everything: writing, SEO analysis, preparing a client meeting.
- Opus at higher effort as soon as Claude chains tools and writes somewhere: a client spreadsheet, a website, a shared folder.
- Fable for vibe coding sessions, when I build a multi-file app.
- Haiku for a quick question in the chat, when I want an instant answer and nothing more.
If you are on the free plan, the same logic applies with Sonnet instead of Opus: medium effort by default, high when the stakes justify it. And if you are still torn between Claude and the competition, I compared the two tools use case by use case in Claude vs ChatGPT. My next video (in French) will put ChatGPT's models through the same test.
Frequently asked questions
Which Claude model should I choose?
On the free plan, Sonnet: it covers writing, summarizing, document analysis and simple code. On a paid plan, Opus by default: it does almost everything Fable does for a fraction of the cost, and it handles multi-step tasks better. Haiku is for quick questions, Fable for large coding projects and tasks Opus cannot finish.
What is the difference between Haiku, Sonnet, Opus and Fable?
The four models share the same interface and the same tools. They differ in speed, reasoning depth and price: Haiku 4.5 is the fastest, Sonnet 5.5 covers everyday use, Opus 5.5 handles complex work and Fable 5.1 is the most capable. On the API, Sonnet costs twice as much as Haiku, Opus four times, Fable ten times.
Which Claude models are available on the free plan?
The free plan gives access to Sonnet and Haiku. Opus is available from the Pro subscription, at $20 per month or $17 per month billed annually. Fable is included in Max, up to half of the weekly limit, and can be used on Pro with usage credits billed on top.
Is Fable worth it compared to Opus?
Rarely. In my tests, Opus had the best business insight on a freelance day rate calculator, while Fable delivered a more technical interface without that insight. Fable is justified for building an app through vibe coding and for very long tasks where Opus hits its ceiling. The rest of the time, it eats your usage without a visibly better result.
What is Claude Mythos and why can't I access it?
Mythos 5.1 is the same model as Fable 5.1, without some of the safeguards, especially in cybersecurity. Access is restricted to vetted organizations that need it, in cybersecurity and the life sciences. It does not appear in the model picker of any consumer plan, not even Max at $200 per month.
What does the effort level do in Claude?
The effort level (low, medium, high, extra, max) sets how much thinking time the model gives itself before answering. It does not make the model smarter, but it lets it search and check more. A response can go from two minutes at low effort to thirty minutes or more at max effort, with usage consumption to match.
Which Claude model uses the least of my usage limit?
Haiku, followed by Sonnet. Each message eats into your limit in proportion to the model and the effort level: Fable at max effort is the most expensive setting. To make a Pro subscription last, keep Sonnet or Opus at medium effort by default, and change the effort level before changing the model.
Put the right model on the right task, across your team
Choosing the tools, tuning the models, building automations that hold up in production: I train teams in the real-world use of Claude and design the workflows that save them time.
Written by
Anthony Courtin
Reader reviews
Did you find this useful? Say so, it helps the next readers.
What readers say
Be the first to leave a review.


